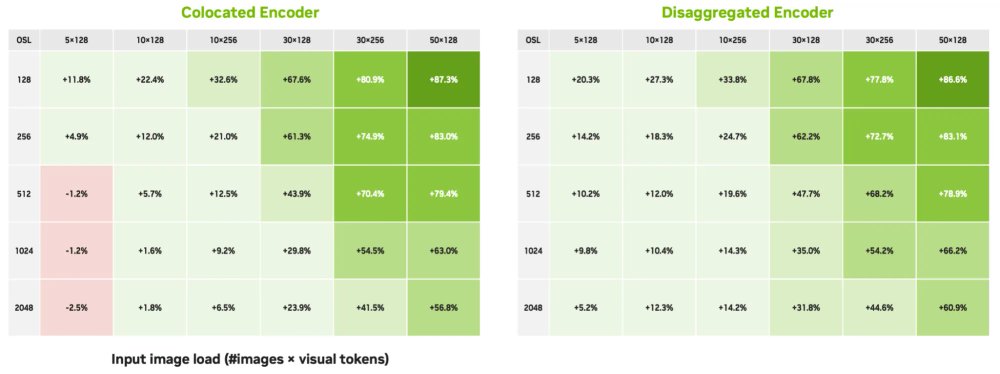
Multimodal models put different demands on vision encoding, prefill and decoding. Separating vision encoding from the other stages can reduce resource contention and help models respond faster, but only for the right workloads. See how EPD disaggregation works, when it helps and what to consider before using it: 📷 ↧ When to Use Encode-Prefill-Decode Disaggregation to Accelerate Mult... Encode-prefill-decode (EPD) disaggregation is an inference optimization technique for multimodal models that separates the vision encoder stage from the prefill and decode stages. It is most effective…
published
Multimodal models put different demands on vision encoding, prefill and decoding. Separating vision encoding from the other stages can reduce resource contention and help models respond faster, but only for the right workloads. See how EPD disaggregation works

Open the original public source →
Latest documented BWB result
$NVDA market result
Exit $NVDA sold Puts for 95% profit
Historical results are not a promise of future performance. Trading involves substantial risk.This public post is a timestamped information archive, not personalized financial advice. Alerts can change as markets move. Join Billy's private group for the complete daily stream and follow-through.