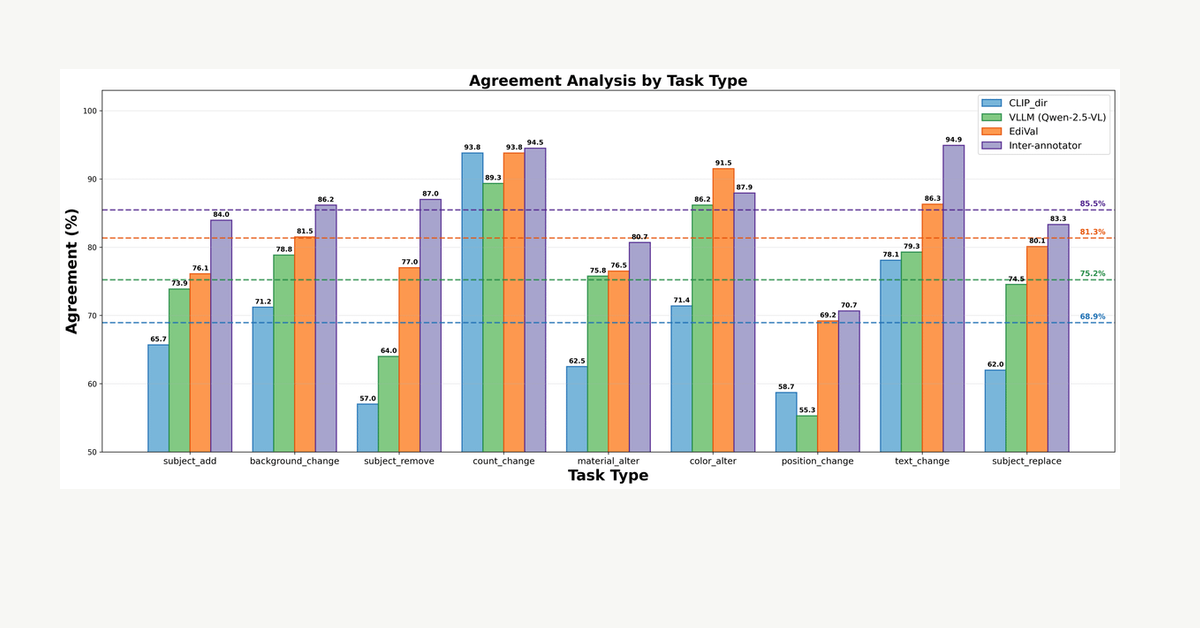
Evaluating image editing models with a single score hides the nuance behind a lower score. EdiVal-Agent (ICLR 2026) splits evaluation across instruction following, content consistency, and visual quality. Its agentic judge reached 81.3% agreement with human judgments, compared with 75.2% for a VLM-only evaluator and 68.9% for CLIP dir. ↧ Closing the loop: agentic evaluation for image editing foundation m... EdiVal-Agent uses agentic AI to evaluate image editing models turn-by-turn, revealing instruction-following failures a single score would miss.
published
Evaluating image editing models with a single score hides the nuance behind a lower score. EdiVal-Agent (ICLR 2026) splits evaluation across instruction following, content consistency, and visual quality. Its agentic judge reached 81.3% agreement with human ju
Open the original public source →
Latest documented BWB result
See Billy's timestamped results and follow-through.
Review the latest gains posts, original timestamps, and proof images published by Banking With Billy.
Historical results are not a promise of future performance. Trading involves substantial risk.This public post is a timestamped information archive, not personalized financial advice. Alerts can change as markets move. Join Billy's private group for the complete daily stream and follow-through.