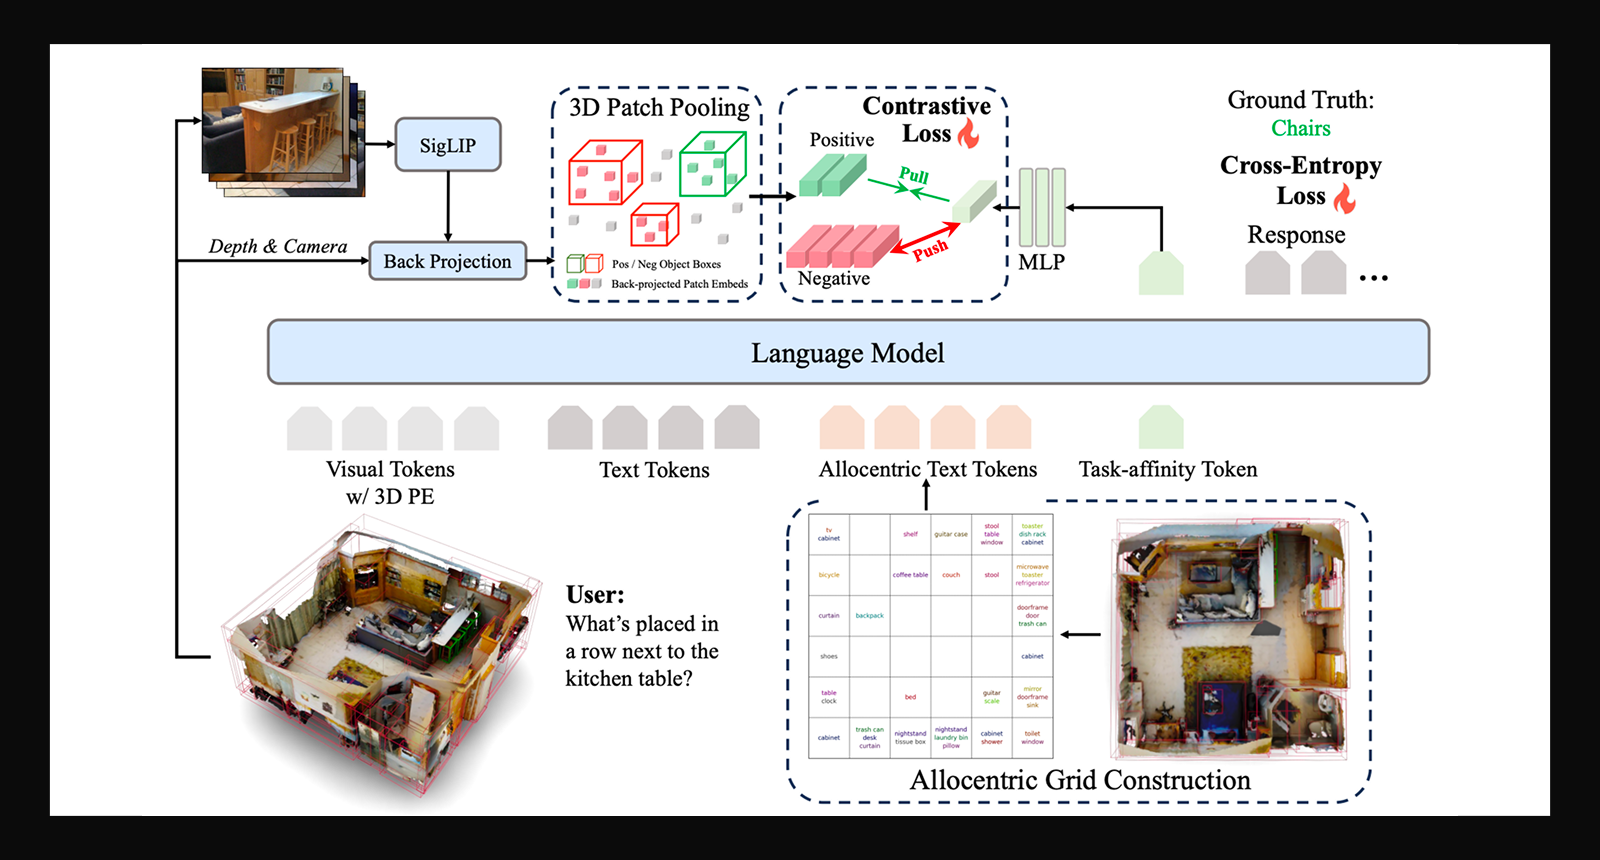
Ask a 3D vision-language model what's near the table and in front of the curtain, and it might guess "sewing machine." The right answer is a tray rack. CVP (UC San Diego + Lambda, WACV 2026) fixes this with a target-affinity token for task-relevant objects and an allocentric grid for global context. Against Video-3D-LLM: • SQA3D EM: 58.6 → 62.3 • Scan2Cap CIDEr: 83.8 → 90.5 • Better on all 5 benchmarks tested Full results across ScanQA, SQA3D, ScanRefer, Multi3DRefer, and Scan2Cap, plus how the central/peripheral split works: ↧ Building multimodal models for spatial reasoning UC San Diego and Lambda introduce CVP, a multimodal model that combines local object focus with global 3D scene awareness for spatial reasoning.
published
Ask a 3D vision-language model what's near the table and in front of the curtain, and it might guess "sewing machine." The right answer is a tray rack. CVP (UC San Diego + Lambda, WACV 2026) fixes this with a target-affinity token for task-relevant objects and
Open the original public source →
Latest documented BWB result
$NBIS market result
Exit $NBIS with $3.25 profit per contract
Historical results are not a promise of future performance. Trading involves substantial risk.This public post is a timestamped information archive, not personalized financial advice. Alerts can change as markets move. Join Billy's private group for the complete daily stream and follow-through.