ICYMI: @Cognition's engineers ran the first customer-executed benchmark on NVIDIA Vera Rubin NVL72. They measured it against their own NVIDIA GB200 NVL72 baseline. Up to 4.8x the total token throughput for SWE-2 inference. 3.8x the output token throughput for reinforcement learning. Agentic coding is an unforgiving workload. Long contexts. High concurrency. Token volumes where cost per token decides what you can ship. For Cognition, those numbers mean more concurrent Devin sessions per GPU, drastically accelerated research loops, and lower cost per session, with no loss in generation speed. The whole stack runs on CoreWeave: training, reinforcement learning, and the inference that serves users. All of it on one platform. The benchmark is theirs. So is the workload. ▻ ↧ First Vera Rubin NVL72 Customer Sees 4.8x Throughput CoreWeave Now in limited availability on CoreWeave, NVIDIA Vera Rubin NVL72 boosts token throughput for Cognition's inference and reinforcement learning workloads.
published
ICYMI: @Cognition's engineers ran the first customer-executed benchmark on NVIDIA Vera Rubin NVL72. They measured it against their own NVIDIA GB200 NVL72 baseline. Up to 4.8x the total token throughput for SWE-2 inference. 3.8x the output token throughput for
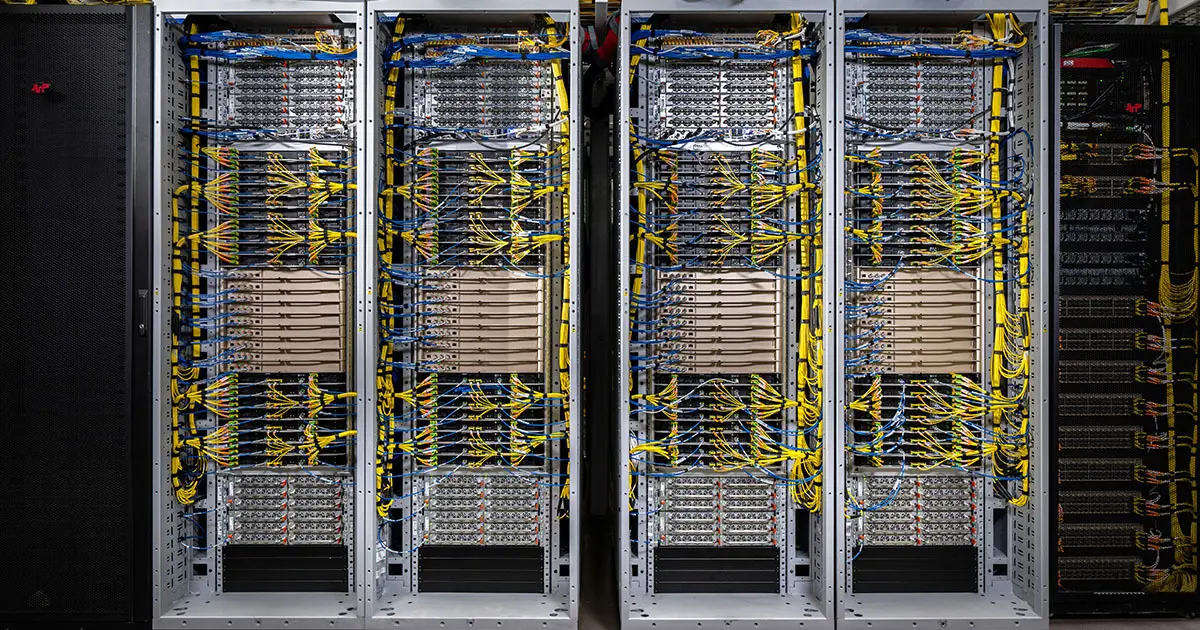
Open the original public source →
Latest documented BWB result
BWB member result
Exit /ES with a 14 Pt (56 tick) profit
Historical results are not a promise of future performance. Trading involves substantial risk.This public post is a timestamped information archive, not personalized financial advice. Alerts can change as markets move. Join Billy's private group for the complete daily stream and follow-through.