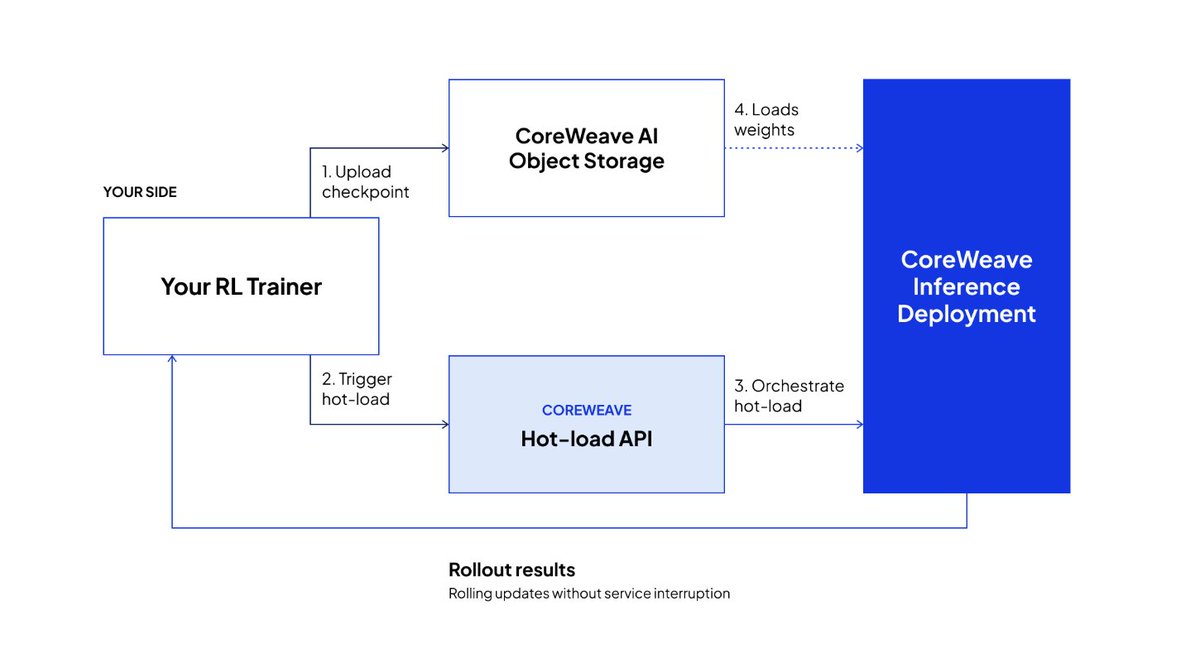
In reinforcement learning, inference is part of the training loop. Every checkpoint used to mean a redeploy, and the trainer waited. CoreWeave RL Rollouts load the new weights into a live deployment without touching in flight requests, about 15x faster than a redeploy cycle. @nvidia and @youdotcom used it to post train Nemotron 3.5 Lightning for web search and lifted BrowseComp accuracy from 36.97% to 45.45% while cutting tool calls by 30.24%. Full breakdown here: 📷 ↧ Closing the Inference to Post-Training Loop CoreWeave Blog
published
In reinforcement learning, inference is part of the training loop. Every checkpoint used to mean a redeploy, and the trainer waited. CoreWeave RL Rollouts load the new weights into a live deployment without touching in flight requests, about 15x faster than a
Open the original public source →
Latest documented BWB result
$NVDA market result
Exit $NVDA with $3 profit per share
Historical results are not a promise of future performance. Trading involves substantial risk.This public post is a timestamped information archive, not personalized financial advice. Alerts can change as markets move. Join Billy's private group for the complete daily stream and follow-through.