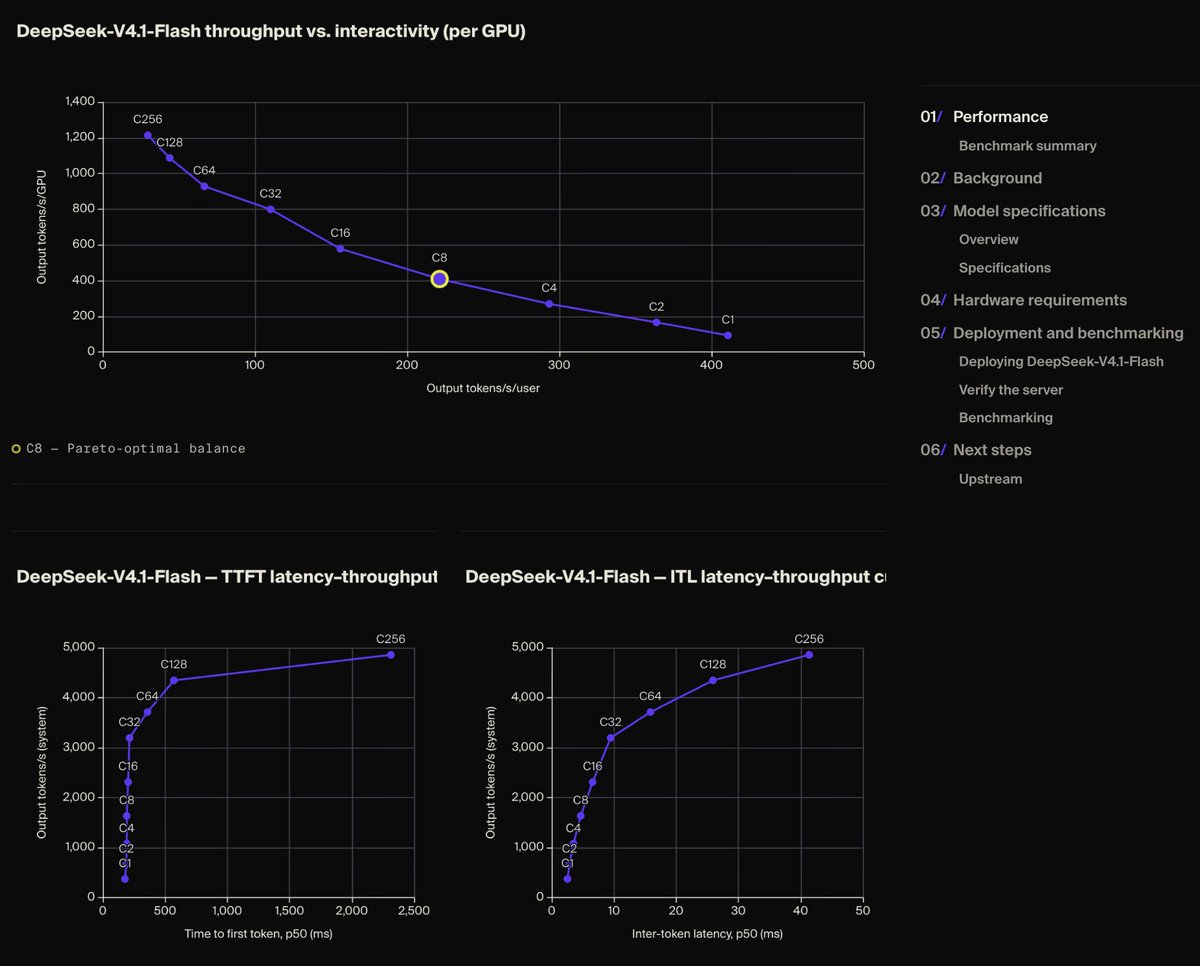
Today we are excited to announce a fresh update on the Lambda Model Cards! Understanding how serving models requires more than knowing the raw tokens/s, and serving real users means caring about more than just concurrency at 1. As of today, our model cards now showcase benchmarks off of @NVIDIAAI's AIPerf benchmarking package on minimal Lambda hardware. With this, you can now properly get an understanding of how your model deployments will behave at certain user thresholds, what its interactivity will look like, and know when you need to scale up to more replicas. 📷 ↧ Inference models Lambda's catalog of model cards for the LLMs that matter. Search by model name to get architecture breakdowns, hardware requirements, deployment guides, and throughput benchmarks on NVIDIA GPUs.
published
Today we are excited to announce a fresh update on the Lambda Model Cards! Understanding how serving models requires more than knowing the raw tokens/s, and serving real users means caring about more than just concurrency at 1. As of today, our model cards now
Open the original public source →
Latest documented BWB result
See Billy's timestamped results and follow-through.
Review the latest gains posts, original timestamps, and proof images published by Banking With Billy.
Historical results are not a promise of future performance. Trading involves substantial risk.This public post is a timestamped information archive, not personalized financial advice. Alerts can change as markets move. Join Billy's private group for the complete daily stream and follow-through.