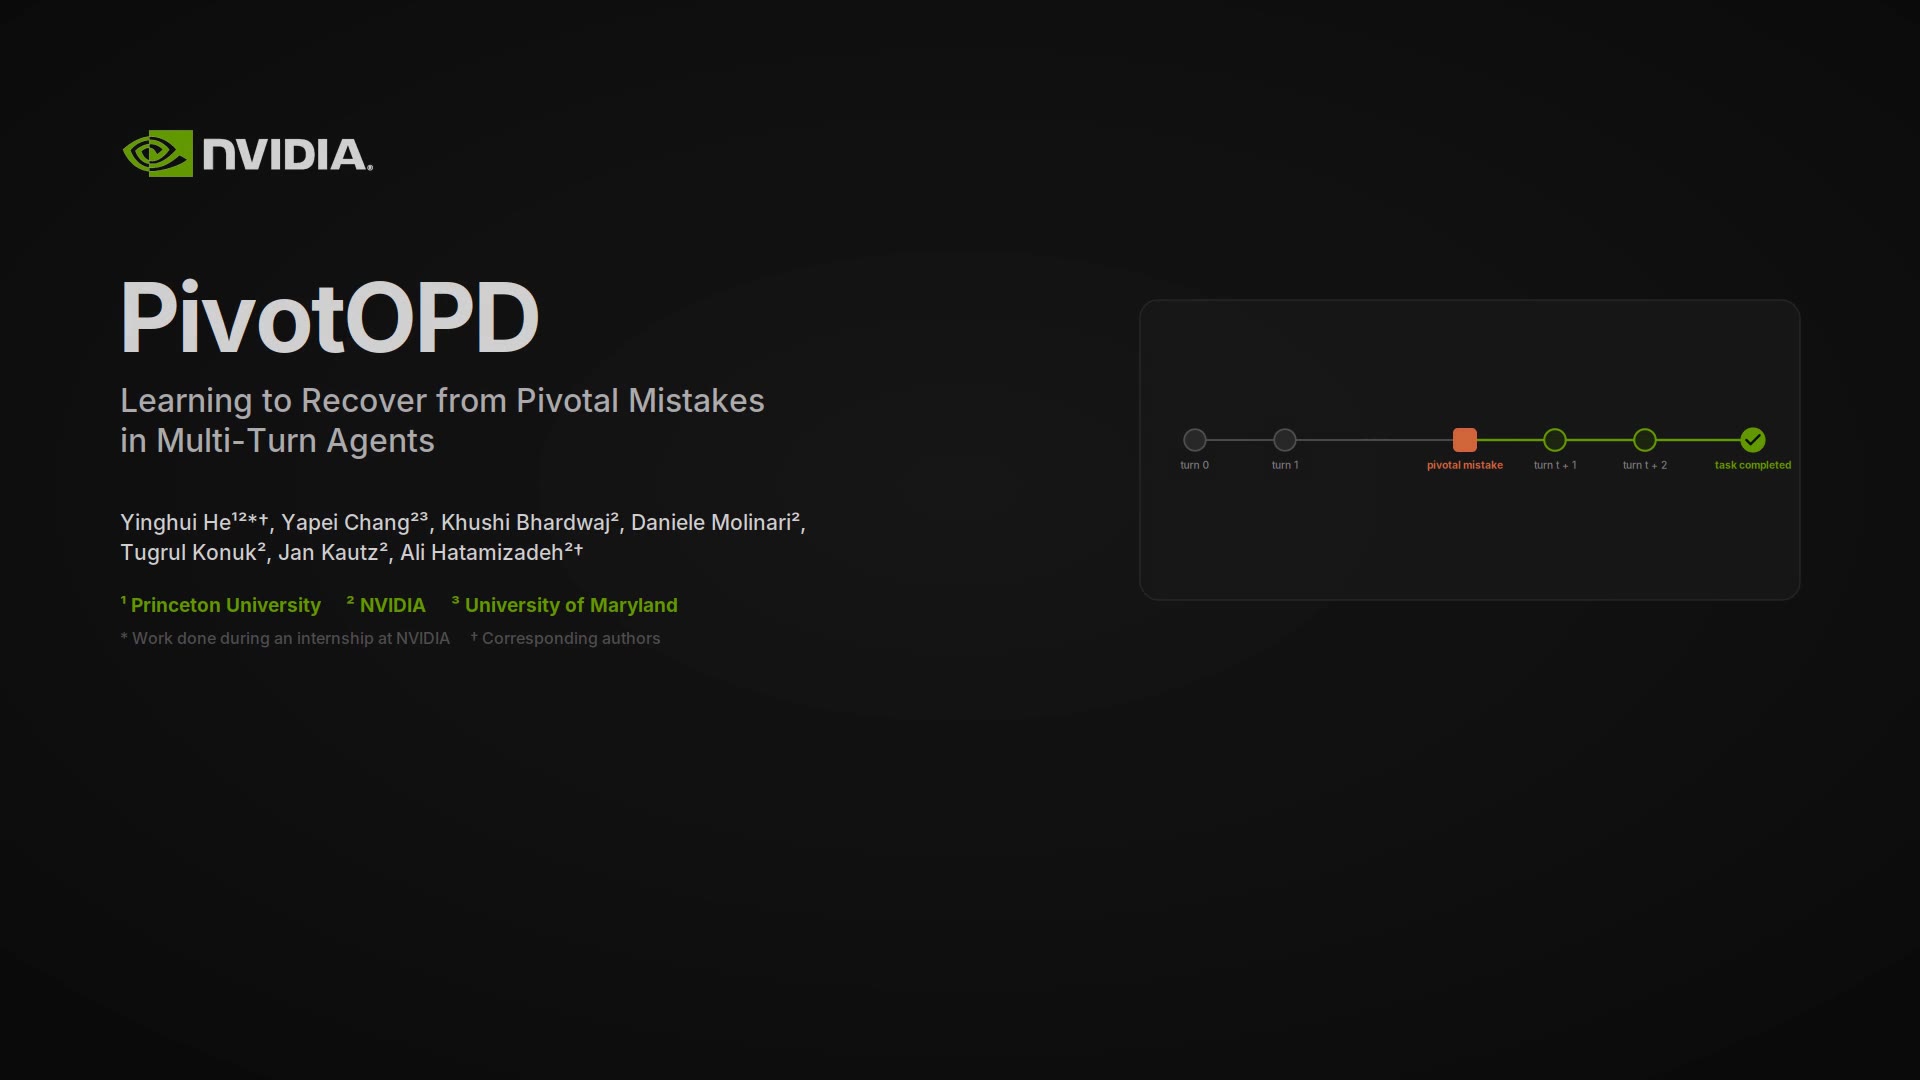
An AI agent makes a mistake early in a task, then keeps going in the wrong direction. Our researchers built PivotOPD to teach agents how to avoid those mistakes and recover when they happen. During training, a teacher model shows the agent a better action and how to get back on track over the next few steps. Read the paper and watch how it works: ▻ ↧ PivotOPD: Learning to Recover from Pivotal Mistakes in Multi-Turn A... An on-policy distillation framework that trains language agents to prevent pivotal mistakes and to recover from them.
published
An AI agent makes a mistake early in a task, then keeps going in the wrong direction. Our researchers built PivotOPD to teach agents how to avoid those mistakes and recover when they happen. During training, a teacher model shows the agent a better action and
Open the original public source →
Latest documented BWB result
$AAPL market result
I sold the $AAPL $320 Puts for 11/20 - $5.30
Historical results are not a promise of future performance. Trading involves substantial risk.This public post is a timestamped information archive, not personalized financial advice. Alerts can change as markets move. Join Billy's private group for the complete daily stream and follow-through.